Data now moves across countless systems, networks, and devices every second of the day. Verifying that this data hasn’t been altered along the way has become just as critical as keeping it confidential.
Cryptographic hashing plays a specific and essential role in this verification process. It serves a purpose distinct from the encryption methods most people associate with cryptography more broadly.
Understanding this distinction matters for anyone building or maintaining digital systems. The two techniques solve different problems, and confusing them can create real security gaps.
In this article we cover what cryptographic hashing actually does, how it differs from encryption, where it’s applied in practice, and why this distinction matters for anyone working with digital systems.
Table of Contents
What Cryptographic Hashing Actually Does
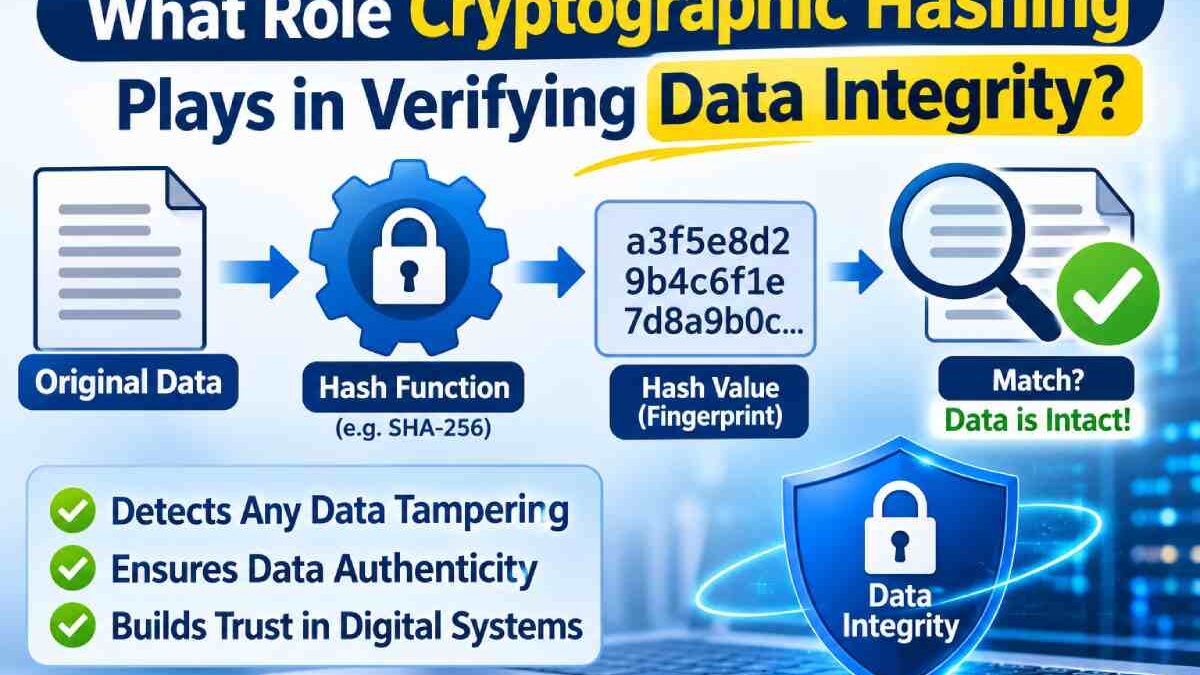
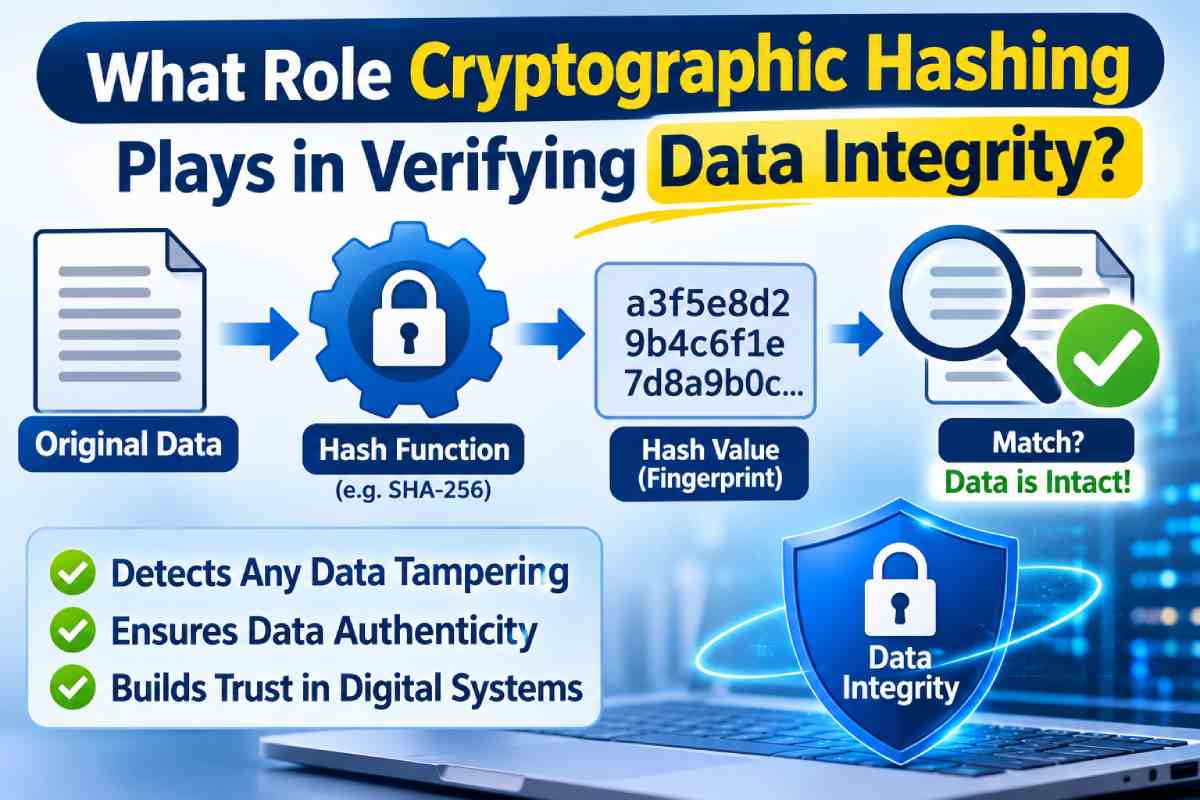
A cryptographic hash function takes an input of any size and produces a fixed-length output called a hash. That hash acts as a unique digital fingerprint for the original data.
Readers new to the underlying math may find this overview of how cryptography works useful before going further. It provides helpful context for how hash functions fit into cryptography as a broader field.
Even a tiny change to the original data produces a completely different hash output. This sensitivity to change is exactly what makes hashing effective for detecting alterations, however small they might be.
Hash functions are deliberately designed to be one-way in nature. Reconstructing the original data from the hash alone is computationally impractical, even with significant computing resources applied to the task.
The National Institute of Standards and Technology formalizes this behavior through its FIPS 180-4 standard. This standard defines the SHA-2 family of hash functions widely used across modern computing systems today.
That standardization matters because it gives developers a consistent, well-vetted foundation to build on. Systems using SHA-2 can rely on decades of cryptographic analysis rather than untested, proprietary hashing approaches.
How Hashing Differs From Encryption
Encryption is designed to be reversible by design, transforming data so it can later be decrypted back into its original form. Anyone holding the correct key can recover the original readable content.
Hashing, by contrast, is intentionally one-directional in its function. Its purpose is verification rather than protecting the confidentiality of data that someone might later need to read again.
This distinction matters because using the wrong tool creates real problems. Hashing data when encryption is actually needed, or the reverse, can leave a system either insecure or effectively unusable.
A system that hashes sensitive data meant for later retrieval, for example, permanently loses access to that original content. There’s no key or process that can reverse a properly designed hash function back to its source.
Where Hashing Is Applied to Verify Data Integrity in Practice
Software distribution commonly uses hashing so users can confirm a downloaded file matches its original source. A published hash value lets users check their downloaded file against it before running or installing anything.
If even a single byte was altered during transfer, or tampered with intentionally, the resulting hash won’t match. This makes hashing a simple but effective safeguard against corrupted or maliciously modified downloads.
Hashing also underlies how passwords are stored securely across most modern systems. Rather than storing the actual password, systems store its hash and compare hashes at login time instead.
This approach means a system can verify a login attempt without ever storing a readable password anywhere. Even if a database is breached, the underlying passwords remain protected by the one-way nature of the hash.
OWASP publishes detailed guidance on secure password storage using hashing correctly, including recommended algorithms and safeguards. Following this guidance helps prevent common mistakes that have led to major password breaches in the past.
Blockchain systems rely heavily on hashing to ensure transaction records cannot be altered without detection. Each block’s hash depends on the data before it, making tampering with historical records immediately apparent.
Why Understanding This Distinction Matters for Anyone Working with Digital Systems
Developers and IT professionals who understand when to apply hashing versus encryption build more secure systems overall. Choosing the right tool for a given task isn’t a minor implementation detail, it shapes the system’s actual security posture.
Misunderstanding this distinction is a common source of security vulnerabilities in practice. Password storage is one of the most frequent areas where this confusion leads to serious, preventable breaches.
As data verification needs grow alongside overall data volume, this knowledge only becomes more relevant. Systems handling more data face more opportunities for corruption, tampering, or accidental alteration along the way.
A clear grasp of cryptographic hashing remains a foundational technical skill as a result. It applies across software development, system administration, and security work more broadly, not just specialized cryptography roles.
Conclusion
Cryptographic hashing plays a distinct and essential role in verifying data integrity, separate from the confidentiality functions of encryption. The two techniques solve different problems using fundamentally different approaches.
As digital systems continue handling greater volumes of sensitive and critical data, understanding how hashing verifies integrity remains a foundational piece of technical literacy. That understanding only grows more valuable as systems scale.
Also Read: How to Choose Strategy Games for Kids